Beyond the six real books, BookNest's data here and in Analytical SQL and Data Warehouses, Batch Processing with Apache Spark, Apache Kafka and Managed Cloud Kafka and Lakehouses, Data Quality and Governance is sample data from generate_orders.py. It uses only the standard library and a seeded random.Random(7), never the clock, so its files are byte-identical on every run. Orders span 1 January 2025 to 30 June 2026 with one to three titles at list price; about 8 percent carry a coupon. Customers have fictional names and @example.com addresses.
python generate_orders.py --out data      # defaults: --orders 100000 --customers 5000 --seed 7
cd data && sha256sum --quiet -c MANIFEST.sha256 && echo "checksums OK"books.json 76 lines 1,937 bytes customers.jsonl 5,000 lines 588,300 bytes orders.jsonl 100,000 lines 23,575,414 bytes order_events.jsonl 390,737 lines 37,277,219 bytes checksums OK
An order holds order_id, customer_id, order_ts, channel, status, currency, an items array of {book_id, qty, unit_price}, a nullable coupon, discount and total. Its lifecycle events go, sorted by time, into order_events.jsonl, like the Kafka 129 topic of Apache Kafka and Managed Cloud Kafka; only order_placed events carry customer_id and total.
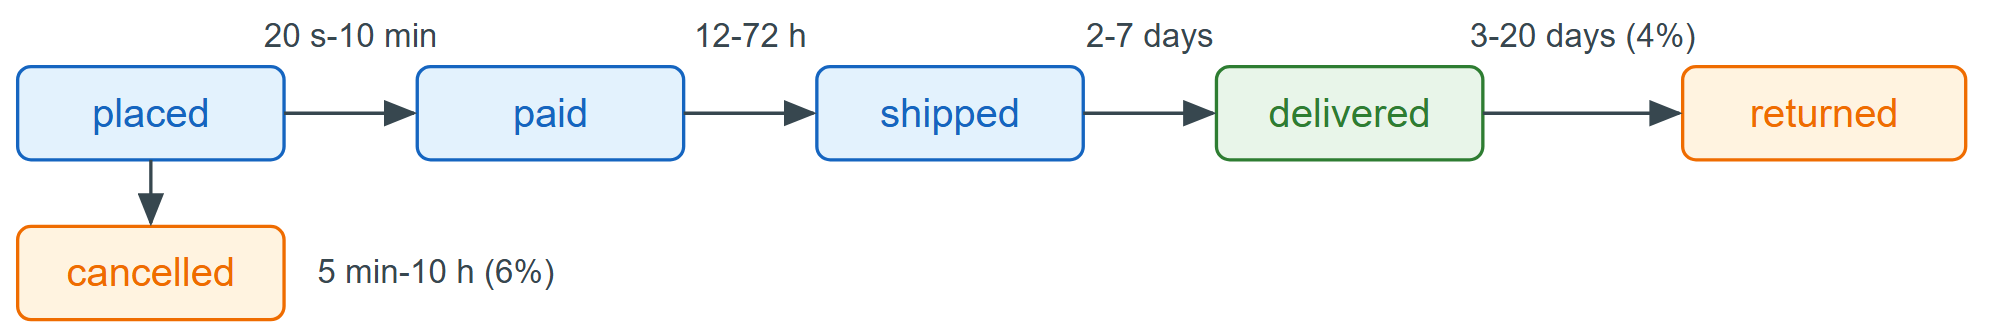
The events comprise 100,000 placed, 94,106 paid, 93,803 shipped, 93,009 delivered, 5,890 cancelled and 3,929 returned. Events after 30 June 2026 are dropped, and status is an order's last surviving event. DuckDB 61,228 's read_json infers order_ts as TIMESTAMP and items as a list of structs, but total as DOUBLE, not DECIMAL: inference is a guess, which the next section replaces with a contract.