Personally identifiable information (PII) can identify a person directly, or combined with other data: a birth date, a postcode and a gender together often single out one person.
| Field | PII? | Why |
|---|---|---|
| Name | Usually | Identifies with context |
| Email address | Yes | Often unique |
| Phone number | Yes | Reaches the person |
| Home address | Yes | Locates the person |
| Passport number | Yes | Government identifier |
| IC/NRIC number | Yes | Also encodes birth date |
| Customer ID | Potentially | Joins back to the person |
| IP address | Context-dependent | Linkable to a household |
| Date of birth | Potentially | Strong quasi-identifier |
| Bank account details | Yes, sensitive | Financial data |
| Password | Credential | Store only a salted hash |
Three techniques reduce the risk:
Masking hides part of a value: john.smith@example.com becomes j***@example.com.
Pseudonymization replaces an identity with an artificial one: John Smith becomes CUSTOMER_18372. A separately kept key or mapping can reverse it, so GDPR still treats it as personal data.
Anonymization removes identifying information so the person can no longer reasonably be identified, for example by aggregating orders into monthly totals. Only truly anonymous data falls outside GDPR.
Apply them before data goes to an external large language model (LLM): identify the PII, drop what the model does not need, mask or pseudonymize the rest, and review what comes back.
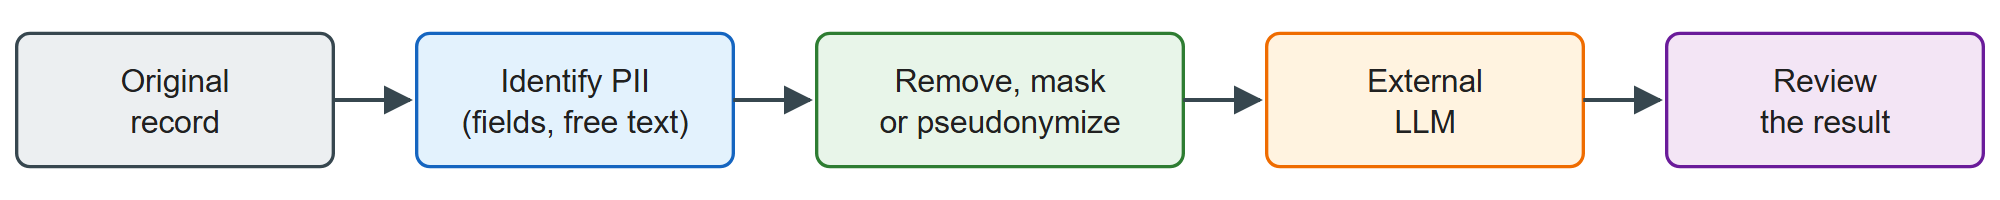
Here is that pipeline for one BookNest support ticket (sample data, not a real person). The pseudonym is a keyed hash (HMAC): the same customer always gets the same ID, and nobody without the key can reverse it.
import hashlib, hmac, json, os, re
KEY = os.environ.get("PSEUDONYM_KEY", "demo-key-keep-in-a-vault").encode()
ticket = {"name": "John Smith", "email": "john.smith@example.com", "ic": "900101-12-5678",
          "total": 150.00, "text": "Refund please, call me on +60 12-345 6789. Book damaged."}
def pseudonym(value):          # same input + same key -> same ID; no mapping table to leak
    digest = hmac.new(KEY, value.encode(), hashlib.sha256).hexdigest()
    return "CUSTOMER_" + str(int(digest[:8], 16) % 100000).zfill(5)
def scrub(text):               # PII hides in free text too (IC first: PHONE would match it)
    for label, pattern in [("IC", r"\b\d{6}-\d{2}-\d{4}\b"), ("EMAIL", r"\S+@\S+"),
                           ("PHONE", r"\+?\d[\d -]{7,}\d")]:
        text = re.sub(pattern, f"[{label}]", text)
    return text
user, domain = ticket["email"].split("@")
payload = {"customer": pseudonym(ticket["email"]), "email": user[0] + "***@" + domain,
           "total": ticket["total"], "text": scrub(ticket["text"])}
print(json.dumps(payload, indent=1)) # name, IC and phone never leave{
"customer": "CUSTOMER_63904",
"email": "j***@example.com",
"total": 150.0,
"text": "Refund please, call me on [PHONE]. Book damaged."
}Regular expressions miss things, such as a name typed into the text. Production pipelines add a trained detector such as Microsoft Presidio (PII Classification and Masking), keep the key in a secrets manager, and send highly sensitive data only to a model deployed inside the organization.