Tools change every few years; the journey data takes does not. Joe Reis and Matt Housley's Fundamentals of Data Engineering (O'Reilly, 2022) describes that journey as the data engineering lifecycle: data is generated in source systems, ingested, stored, transformed and finally served to the people and programs that use it. Storage is not one step in a line but the layer every later stage reads from and writes to, and a set of undercurrents (security, data management, DataOps, architecture, orchestration and software engineering) runs beneath all of it. The Lifecycle's Undercurrents covers those.
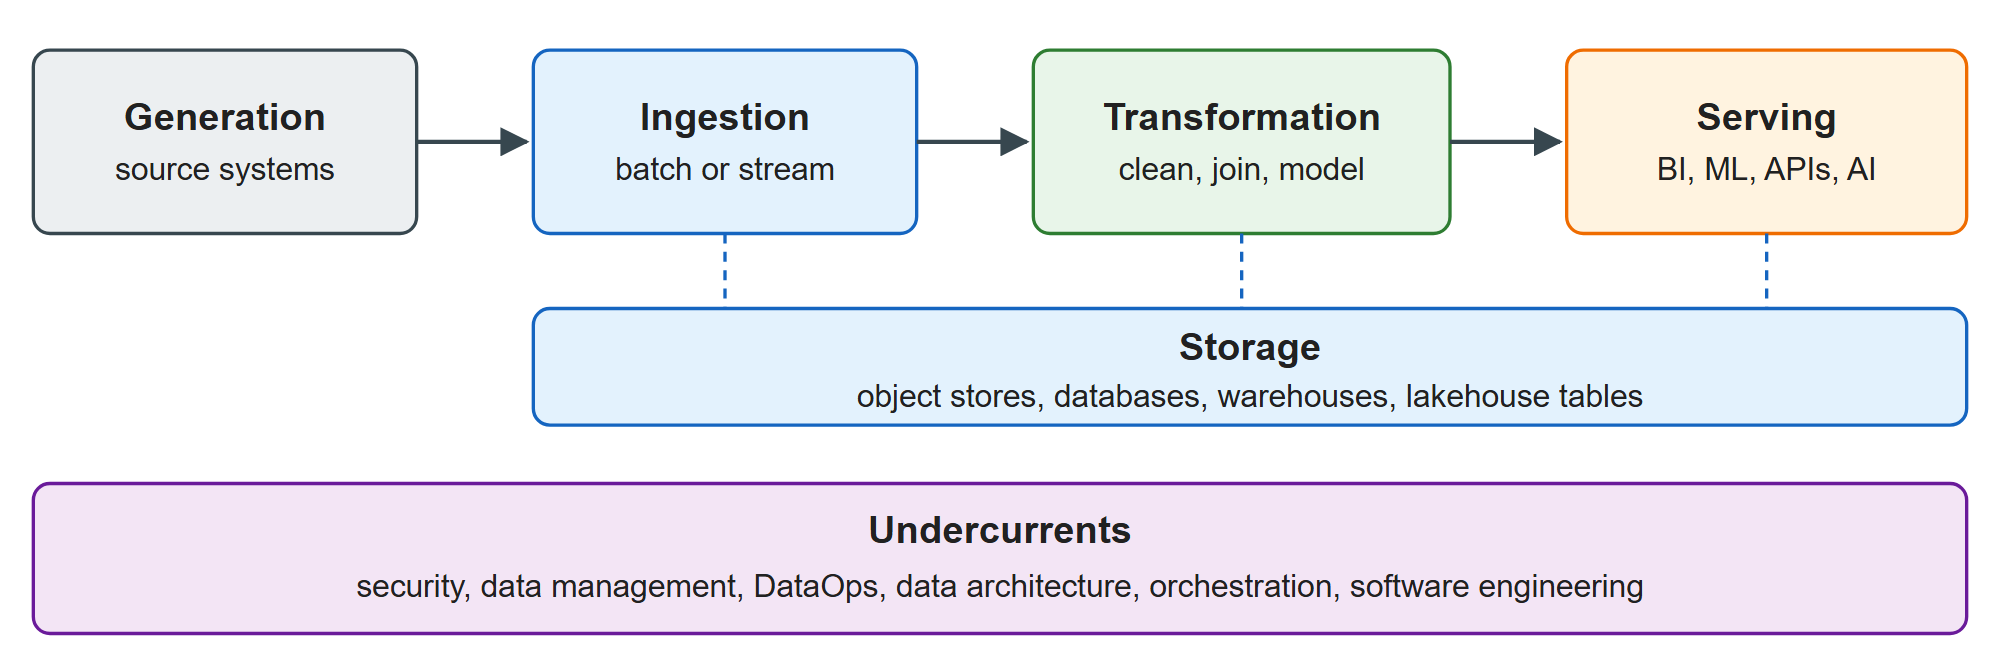
The lifecycle is deliberately tool-neutral. A Kafka 129 topic, an S3 bucket and a PostgreSQL 1,289 table can all play the storage role; Spark 129 , dbt 37,942 and a ten-line DuckDB 61,228 query can all transform. Thinking in stages first and tools second keeps you from building a pipeline around whichever product is fashionable this year.