Every action recomputes its DataFrame from the source (Transformations Versus Actions). cache() and persist(level) keep the computed partitions on the executors for later actions; both are lazy, and unpersist() frees them.
import time
from pyspark import StorageLevel
def timed(label, df):
    t0 = time.perf_counter()
    df.agg(F.sum("qty"), F.countDistinct("customer_id")).first()
    print(f"{label:<28} {time.perf_counter() - t0:5.2f}s")
delivered = lines.where("status = 'delivered'")
timed("Parquet scan, warm-up", delivered)
timed("Parquet scan", delivered)
delivered.cache()                                 # lazy: marks the plan for caching
timed("first action fills the cache", delivered)
timed("served from the cache", delivered)
orders.persist(StorageLevel.DISK_ONLY).count()    # two more entries for the Storage tab
customers.persist(StorageLevel.MEMORY_ONLY).count()
Output
Parquet scan, warm-up        11.52s
Parquet scan                  2.76s
first action fills the cache  9.03s
served from the cache         1.50s
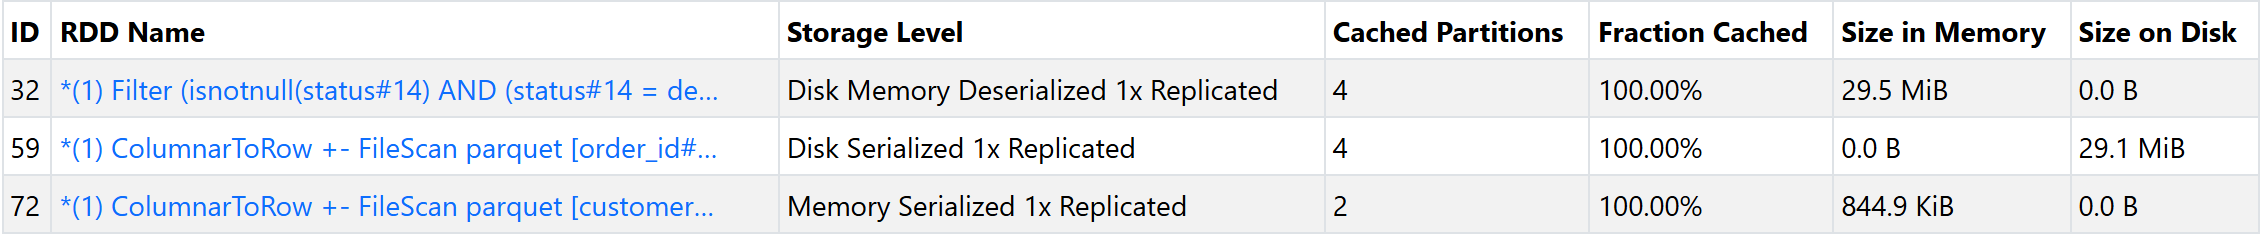
Filling the cache cost three plain scans; later actions ran about twice as fast. The delivered lines took 29.5 MiB of memory, more than the 20 MB Parquet 129 table: the cache keeps Spark 129 's own compressed column batches.