After 300 MB of reserved heap, spark.memory.fraction (0.6) of the rest forms the unified region shared by execution (shuffles, joins, sorts, aggregations) and storage (cache, broadcasts); the other 40% is user memory for your objects and Spark 129 's metadata. Outside the heap, the container needs overhead memory for the JVM itself, Python workers and network buffers.
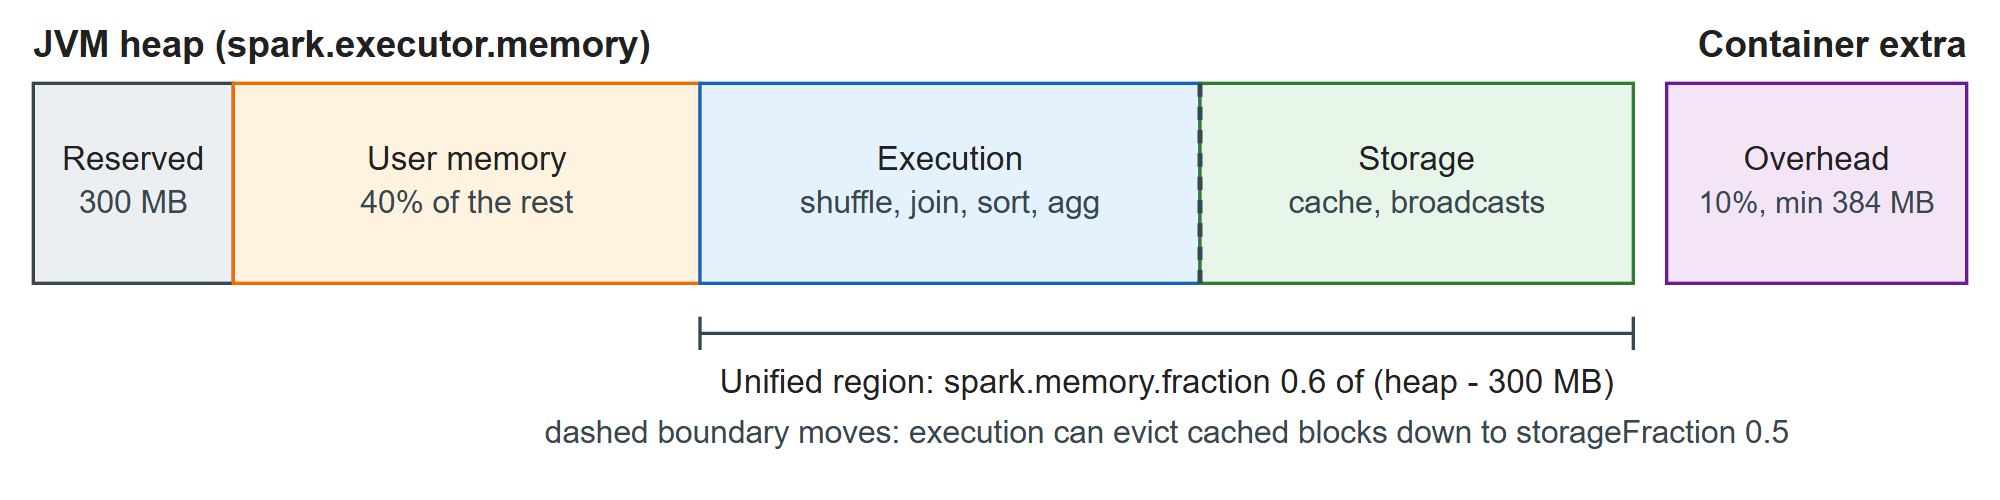
Either side borrows free memory from the other; execution can evict cached blocks down to spark.memory.storageFraction (0.5), never the reverse. When execution memory runs out, operators spill to disk instead of failing, so an OutOfMemoryError usually means memory Spark does not manage: user objects, a huge group, results collected to the driver, or overhead outside the heap.