The second workload joined order lines to a six-row status table with broadcasting and AQE's skew handling switched off, so every delivered line, 89% of them, had to meet in one task. Open the join stage on the Stages tab and read its summary metrics.
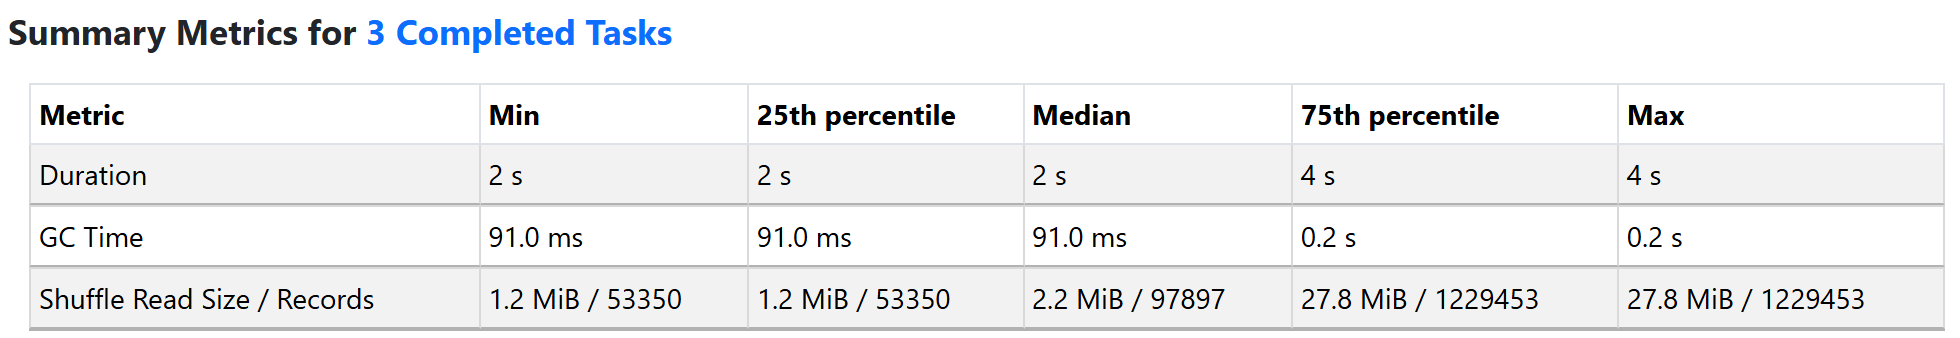
The signature of skew is the gap between the median and maximum columns: one task read 1,229,453 records (27.8 MiB) while the median task read 97,897, and the slowest task set the stage's duration. Healthy stages have maximums within a small multiple of the median. Confirm by sorting the task table by shuffle read, then find the hot key with a GROUP BY count (Diagnosing Data Skew). On a single 4-core machine the durations understate the problem: with only three tasks, the cores never wait long. On a cluster with 200 tasks, 199 finish in seconds and the stage waits minutes for the last one, visible as a long single bar in the stage's Event Timeline.