innerHTML is an element's inner markup, outerHTML adds its own tags, and textContent is plain text that never parses. Assigning innerHTML rebuilds every child, so innerHTML += wipes typed input and listeners. DOMParser parses into a separate, inert Document; XMLSerializer serializes nodes back. Two newer methods:
setHTMLUnsafe(html) is innerHTML plus declarative shadow roots (<template> and <slot>); Document.parseHTMLUnsafe() is its DOMParser twin. Baseline since September 2025.
setHTML(html, { sanitizer }), the Sanitizer API, always strips <script>, <iframe>, <object>, <embed> and event-handler attributes, whatever the configuration says. It ships in Chrome 1 and Edge 146 and Firefox 148 555 , not yet Safari 10 , so feature-detect it.
<pre id="out" style="font-size:12px;margin:0"></pre>
<script>
  const html = '<b>Hi</b><a href="#" onclick="steal()">Go</a><script>steal()<\/script>';
  const box = document.createElement('div');
  box.innerHTML = html;
  const lines = [`innerHTML:  ${box.innerHTML}`];
  if ('setHTML' in box) lines.push(`setHTML:    ${(box.setHTML(html), box.innerHTML)}`);
  const doc = new DOMParser().parseFromString(html, 'text/html');
  lines.push(`DOMParser:  ${doc.body.childElementCount} elements in an inert document`,
    `serialized: ${new XMLSerializer().serializeToString(doc.body.firstChild)}`);
  document.querySelector('#out').textContent = lines.join('\n');
</script>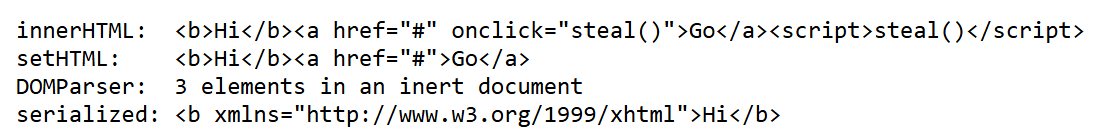
Inserted scripts never run, but the surviving onclick fires on click: a cross-site scripting hole. Treat innerHTML and ...Unsafe methods as injection sinks (Trusted Types, Sandboxing and Trusted Types; sanitizers, Sanitization and XSS Defence).