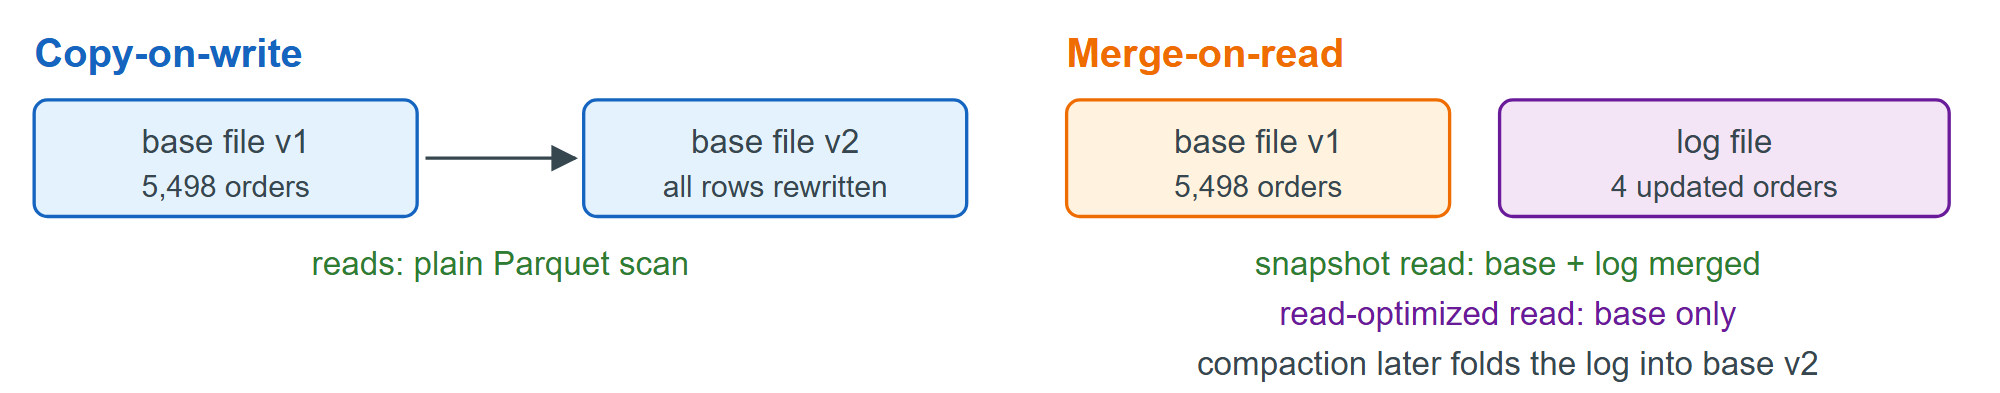
Hudi 129 makes the choice that Iceberg 129 and Delta expose as a write mode into a table type. A copy-on-write (COW) table rewrites a file's whole new version, a base file, whenever a record in it changes: reads stay plain Parquet 129 scans, writes pay. A merge-on-read (MOR) table appends changes to row-based log files beside the base file, and readers merge them on the fly until compaction folds them into a new base file: writes are cheap, reads pay. Every record carries a record key (here order_id) and an ordering field that decides which version wins when two arrive for the same key. The script loads June's 5,498 orders into one table of each type, then upserts the four pending orders as shipped:
"""June's orders as a Hudi copy-on-write and a merge-on-read table, then one upsert to each."""
import os
from pyspark.sql import functions as F
from hspark import spark
H = "/home/dev/v7-l1/ch08/hudi"
june = (spark.read.parquet("/mnt/d/Books/Data Engineering/demos/ch03/out/orders.parquet")
        .drop("items").where("order_ts >= '2026-06-01'").withColumn("rev", F.lit(1)))
shipped = june.where("status = 'pending'").withColumns({"status": F.lit("shipped"),
                                                        "rev": F.lit(2)})   # a newer revision
for kind in ("COPY_ON_WRITE", "MERGE_ON_READ"):
    name = "orders_" + kind[:3].lower()            # orders_cop, orders_mer
    w = lambda df: (df.write.format("hudi").option("hoodie.table.name", name)
        .option("hoodie.datasource.write.table.type", kind)
        .option("hoodie.datasource.write.recordkey.field", "order_id")
        .option("hoodie.datasource.write.precombine.field", "rev"))
    w(june).mode("overwrite").save(f"{H}/{name}")                     # bulk load: commit 1
    w(shipped).option("hoodie.datasource.write.operation", "upsert").mode("append").save(
        f"{H}/{name}")                                                 # 4 updates: commit 2
    files = [f for d, _, fs in os.walk(f"{H}/{name}") if ".hoodie" not in d
             for f in fs if not f.endswith(".crc")]
    count = lambda q: spark.read.format("hudi").option("hoodie.datasource.query.type", q) \
        .load(f"{H}/{name}").where("status = 'pending'").count()
    print(f"{kind:<14} parquet {sum(f.endswith('.parquet') for f in files)}, log "
          f"{sum('.log.' in f for f in files)} | pending: snapshot {count('snapshot')}, "
f"read_optimized {count('read_optimized')}")COPY_ON_WRITE parquet 2, log 0 | pending: snapshot 0, read_optimized 0 MERGE_ON_READ parquet 1, log 1 | pending: snapshot 0, read_optimized 4
The COW table wrote a second Parquet version of its only file group to change four rows; the MOR table wrote one small log file instead. A snapshot query merges the log and sees no pending orders, while a read-optimized query reads base files only, faster but four updates behind until compaction runs. That trade-off, fresh data for cheap writes, is why MOR suits streaming CDC and COW suits read-heavy tables.