The Iceberg 129 catalog of Iceberg Catalogs knows one fact per table: where its current metadata file is. A data catalog (or metadata platform) knows what people need: description and owner, which columns hold personal data, which jobs feed the table and which dashboards read it, and whether its checks passed. Metadata is technical (schemas, partitions), business (descriptions, owners, glossary terms), operational (runs, freshness, lineage) or social (query counts that rank search results).
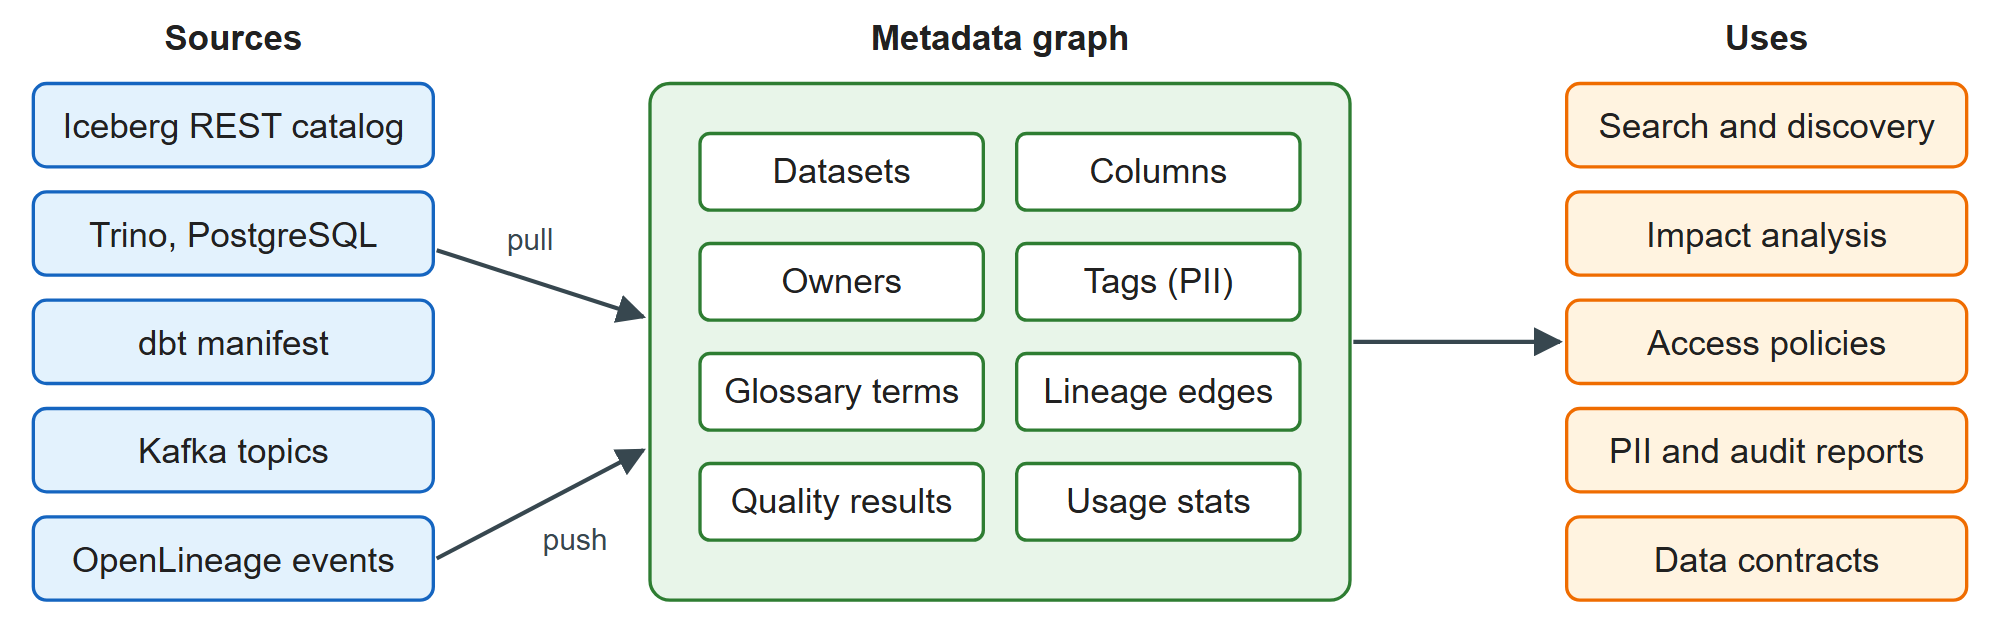
Pull ingestion runs a connector on a schedule that reads schemas and statistics; push ingestion has producers report changes as they happen, such as OpenLineage events or a job that tags columns after a classification run. Production catalogs use both. The hard part is the habit, not the software: an owner and a description on every table, written in the pull request that creates it.