DataHub 559,249 (https://github.com/datahub-project/datahub 12,790 ) (Apache-2.0, about 12,800 stars) started at LinkedIn and is now led by the company DataHub (Acryl Data until May 2025); version 1.7.0.1 (3 September 2026) ran here. Its metadata service (GMS) stores each entity's aspects (schema, owners, tags) in MySQL 524 , indexes them in OpenSearch and emits every change on Kafka 129 . Connectors (pip 21,050 install 'acryl-datahub[iceberg]', CLI 1.7.0.14) pull metadata; pipelines push it through the REST API or Python SDK. catalog/datahub.yml (the quickstart Compose file as project l1-datahub, UI on port 31902) used 4.4 GiB at rest, more than the lakehouse. A recipe points the PyIceberg-based connector at BookNest's REST catalog:
source:                                      # DataHub recipe: BookNest's Iceberg tables
  type: iceberg
  config:
    catalog:
      lake:                                  # passed to PyIceberg's load_catalog()
        type: rest
        uri: http://localhost:31181
        s3.endpoint: http://localhost:31900
        s3.access-key-id: booknest-admin
        s3.secret-access-key: ${MINIO_PASS}
    profiling: {enabled: true}               # row counts, nulls, min/max per column
sink: {type: datahub-rest, config: {server: "http://localhost:31808"}}
datahub ingest -c catalog/iceberg_recipe.yml reported 'tables_scanned': 8 and "Pipeline finished with at least 1 warnings; produced 77 events in 3.51 seconds"; the warning was a PyIceberg decoding error that skipped profiling of orders. Pull ingestion knows nothing of personal data, so catalog/tag_pii.py pushes PII Classification and Masking's classification through the SDK: a PII.<TYPE> tag per detected column, PII.QUASI_IDENTIFIER on two more, and an owner:
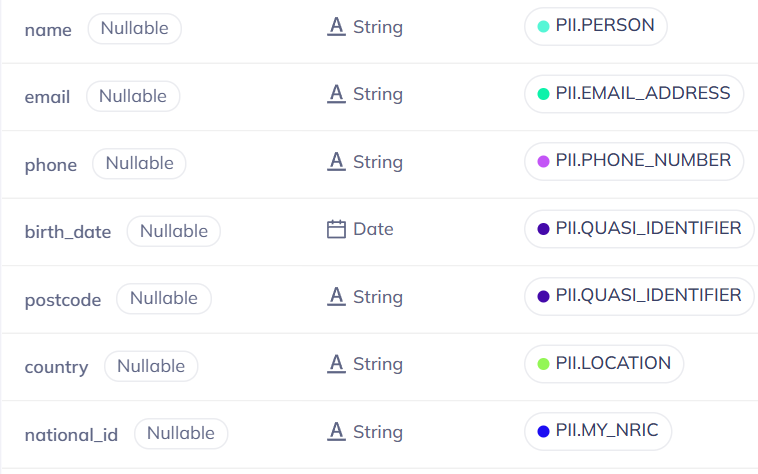
Tags become search filters and policy inputs; DataHub's own policies govern who may edit metadata, not who reads the lake. The hosted DataHub Cloud adds quality monitors and automation on the same core.