Trino 403,499 (https://github.com/trinodb/trino 13,296 ) (Apache-2.0), born at Facebook in 2012 as Presto and renamed after its creators forked it, is a distributed SQL engine with no storage of its own: one coordinator, many workers:
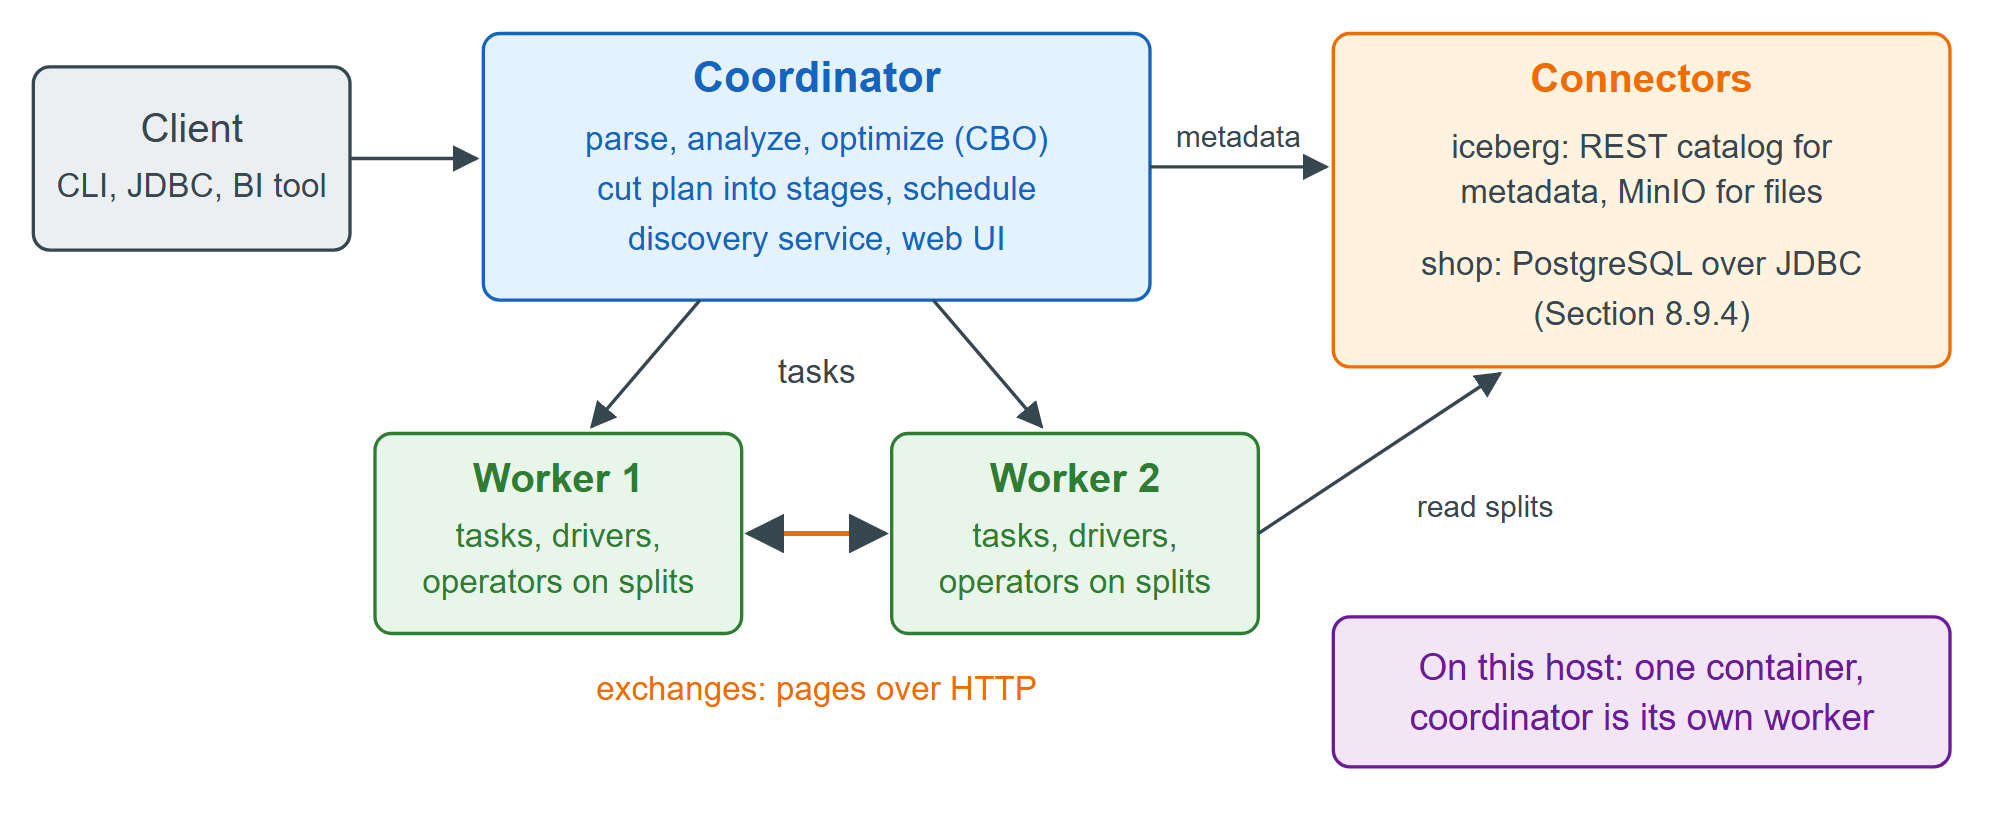
The coordinator plans a query (Optimizer and Federation) and cuts the plan into stages wherever data must be redistributed. Stages run as tasks on workers; a task processes splits (for Iceberg 129 , a range of one data file) through drivers, chains of operators passing columnar pages, and stages trade pages through exchanges, HTTP buffers. All of it is in memory and pipelined, so a dead worker fails the query unless retry-policy=TASK and an exchange manager spilling to object storage make tasks retryable. Connectors supply the data through one interface, so a single query can join Iceberg tables with PostgreSQL 1,289 's.