BookNest gives one reward point per dollar, and on a Double Points Weekend every book's points double: one invocation per book reads one slot and writes another, and the shared total needs an atomic. The doubled values never leave the GPU before a render pass draws them; the read-back only checks the work against JavaScript:
<canvas id="chart" width="480" height="120"></canvas>
<script type="module">
const device = await (await navigator.gpu.requestAdapter()).requestDevice();
const { STORAGE, COPY_SRC, COPY_DST, MAP_READ } = GPUBufferUsage;
const points = device.createBuffer({ size: 64, usage: STORAGE | COPY_SRC | COPY_DST });
const read = device.createBuffer({ size: 64, usage: COPY_DST | MAP_READ });
device.queue.writeBuffer(points, 0, new Uint32Array([15, 40, 24, 19, 16, 21]));  // $ -> pts
const shader = device.createShaderModule({ code: /* wgsl */ `
  struct Points { before: array<u32, 8>, after: array<u32, 7>, total: atomic<u32> }
  @group(0) @binding(0) var<storage, read_write> p: Points;
  @compute @workgroup_size(64) fn double(@builtin(global_invocation_id) id: vec3u) {
    if (id.x >= 6) { return; }                       // 64 invocations, 6 books
    p.after[id.x] = 2 * p.before[id.x];              // each invocation owns one slot
    atomicAdd(&p.total, p.after[id.x]);              // a shared slot needs an atomic
  }
  @group(0) @binding(0) var<storage> bars: array<u32, 16>;
  struct Bar { @builtin(position) pos: vec4f, @location(0) @interpolate(flat) after: u32 }
  @vertex fn vs(@builtin(vertex_index) v: u32, @builtin(instance_index) i: u32) -> Bar {
    let q = array(vec2f(0, 0), vec2f(1, 0), vec2f(0, 1), vec2f(1, 1))[v];
    let x = -0.95 + f32(i % 8) * 0.32 + f32(i / 8) * 0.13 + q.x * 0.12;
    return Bar(vec4f(x, -0.9 + q.y * f32(bars[i]) / 44, 0, 1), i / 8);  // 80 = full height
  }
  @fragment fn fs(bar: Bar) -> @location(0) vec4f {  // before grey, after BookNest blue
    return select(vec4f(0.7, 0.7, 0.7, 1), vec4f(0.08, 0.40, 0.75, 1), bar.after == 1);
  }` });
const compute = device.createComputePipeline({ layout: 'auto', compute: { module: shader } });
const format = navigator.gpu.getPreferredCanvasFormat(), context = chart.getContext('webgpu');
context.configure({ device, format });
const draw = device.createRenderPipeline({ layout: 'auto', vertex: { module: shader },
  fragment: { module: shader, targets: [{ format }] },
  primitive: { topology: 'triangle-strip' } });          // 4 vertices per bar
const bind = (pipeline) => device.createBindGroup({ layout: pipeline.getBindGroupLayout(0),
  entries: [{ binding: 0, resource: points }] });
const encoder = device.createCommandEncoder(), pass1 = encoder.beginComputePass();
pass1.setPipeline(compute), pass1.setBindGroup(0, bind(compute));
pass1.dispatchWorkgroups(1), pass1.end();
const pass2 = encoder.beginRenderPass({ colorAttachments: [{ loadOp: 'clear', storeOp: 'store',
  view: context.getCurrentTexture().createView(), clearValue: [0.96, 0.94, 0.90, 1] }] });
pass2.setPipeline(draw), pass2.setBindGroup(0, bind(draw));
pass2.draw(4, 14), pass2.end();                      // bars read straight from storage
encoder.copyBufferToBuffer(points, read);
device.queue.submit([encoder.finish()]), await read.mapAsync(GPUMapMode.READ);
const v = new Uint32Array(read.getMappedRange());
console.log(`before ${v.slice(0, 6).join(', ')}; after ${v.slice(8, 14).join(', ')}`);
console.log(`total ${v[15]}; JavaScript agrees: ${v.slice(0, 6).every((p, i) =>
  v[8 + i] === 2 * p) && v[15] === 2 * v.slice(0, 6).reduce((a, b) => a + b)}`);
window.__done = true;
</script>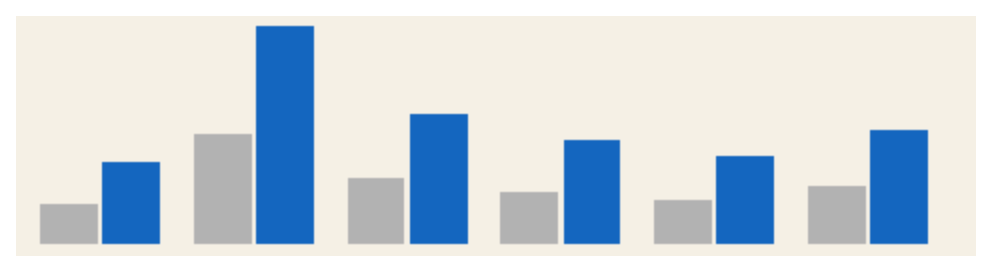
before 15, 40, 24, 19, 16, 21; after 30, 80, 48, 38, 32, 42
total 270; JavaScript agrees: true
One buffer holds the six original values, the doubled ones from byte 32 and the atomic total in the last slot. The compute entry point double and the drawing entry points share one module, each with its own view of binding 0 (read-write and read-only), which WGSL allows because no entry point uses both. The guard id.x >= 6 stops the other 58 invocations from writing past after. Both passes share one command encoder, and WebGPU orders the compute writes before the render pass reads them. Grey bars are the original points, blue ones the doubled points.