A storage texture is written texel by texel with textureStore(), without a render pass, blending or a sampler. Declare it as texture_storage_2d<format, access> with write (the default), read or read_write access; in core WebGPU, read_write works only for r32float, r32sint and r32uint (an rgba8unorm one failed with "does not support storage texture access StorageTextureAccess::ReadWrite"), and the texture-formats-tier2 feature widens the list. A canvas can be a storage texture too, if configured with rgba8unorm and STORAGE_BINDING, so this compute shader paints the canvas directly, one invocation per pixel:
<canvas id="gpu" width="480" height="120"></canvas>
<script type="module">
const device = await (await navigator.gpu.requestAdapter()).requestDevice();
const context = gpu.getContext('webgpu');
context.configure({ device, format: 'rgba8unorm',    // storage needs a non-sRGB rgba format
  usage: GPUTextureUsage.STORAGE_BINDING });           // no RENDER_ATTACHMENT needed
const code = /* wgsl */ `
const palette = array(vec3f(.08, .40, .75), vec3f(.18, .49, .20), vec3f(.94, .42, 0),
                      vec3f(.42, .11, .60), vec3f(.22, .28, .31), vec3f(.78, .16, .16));
@group(0) @binding(0) var canvas: texture_storage_2d<rgba8unorm, write>;
@compute @workgroup_size(8, 8) fn main(@builtin(global_invocation_id) id: vec3u) {
  let size = textureDimensions(canvas);
  if (any(id.xy >= size)) { return; }                  // the grid overshoots the edges
  let p = vec2f(id.xy) - vec2f(f32(size.x) / 2, f32(size.y) + 30);   // rays from below
  let ring = u32(length(p) / 20) % 6;                  // six rings, one per book
  let spoke = step(0.5, fract(atan2(p.y, p.x) * 12 / 3.14159));
  textureStore(canvas, id.xy, vec4f(palette[ring] * (0.8 + 0.2 * spoke), 1));
}`;
const pipeline = device.createComputePipeline({ layout: 'auto',
  compute: { module: device.createShaderModule({ code }) } });
const encoder = device.createCommandEncoder(), pass = encoder.beginComputePass();
pass.setPipeline(pipeline);
pass.setBindGroup(0, device.createBindGroup({ layout: pipeline.getBindGroupLayout(0),
  entries: [{ binding: 0, resource: context.getCurrentTexture().createView() }] }));
pass.dispatchWorkgroups(Math.ceil(gpu.width / 8), Math.ceil(gpu.height / 8));
pass.end();
device.queue.submit([encoder.finish()]);
await device.queue.onSubmittedWorkDone();
window.__done = true;
</script>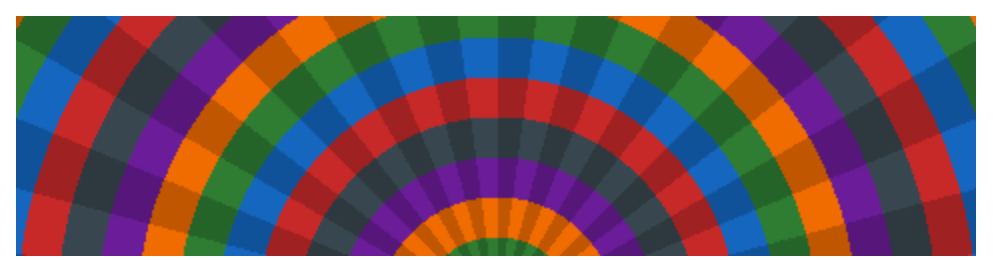
The dispatch rounds up to whole 8 x 8 workgroups, so invocations past the edge return early. Storage textures are the natural output of image filters (Cover Blur), procedural textures and compute mipmap generators.