A diacritic is a mark added to a letter, such as the accent in é. Unicode can store é as the single precomposed character U+00E9, or as e followed by U+0301 COMBINING ACUTE ACCENT. Combining marks live mainly in the block U+0300 to U+036F (decimal 768 to 879); place one after any character with a numeric reference. Marks stack, which is how "Zalgo" text piles them above and below a letter.
| Mark | Reference | Result | Mark | Reference | Result |
|---|---|---|---|---|---|
| Grave, acute | à á | à á | Caron, cedilla | č ç | č ç |
| Circumflex, tilde | â ñ | â ñ | Dot below, ring | ạ å | ạ å |
| Diaeresis | ü | ü | Long stroke | a̶ | a̶ |
<p style="font: 22px Georgia, serif">
Việt Nam · s̶t̶r̶i̶k̶e̶ ·
Z͓͑͒à́̂̃l̈̊ģo̶</p>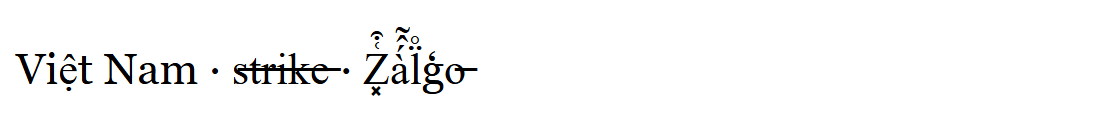
The two encodings look identical but compare as different strings, so a search for "café" can miss "café". Normalize input before comparing or storing it: combined.normalize('NFC') composes, 'NFD' decomposes, and str.normalize('NFD').replace(/\p{M}/gu, '') turns "Crème brûlée" into the search key "Creme brulee". To count characters as a reader sees them, use Intl.Segmenter (Baseline since April 2024) rather than length. Strip marks only for search keys and slugs, never for display: in Vietnamese or Czech the mark changes the word.